Skip to content

Marblehead, MA

42.5006° N  70.8659° W

02Projects

Projects

Three products in production, a handful of ML and systems experiments, and a fix merged into pandas.

I — In production

Products

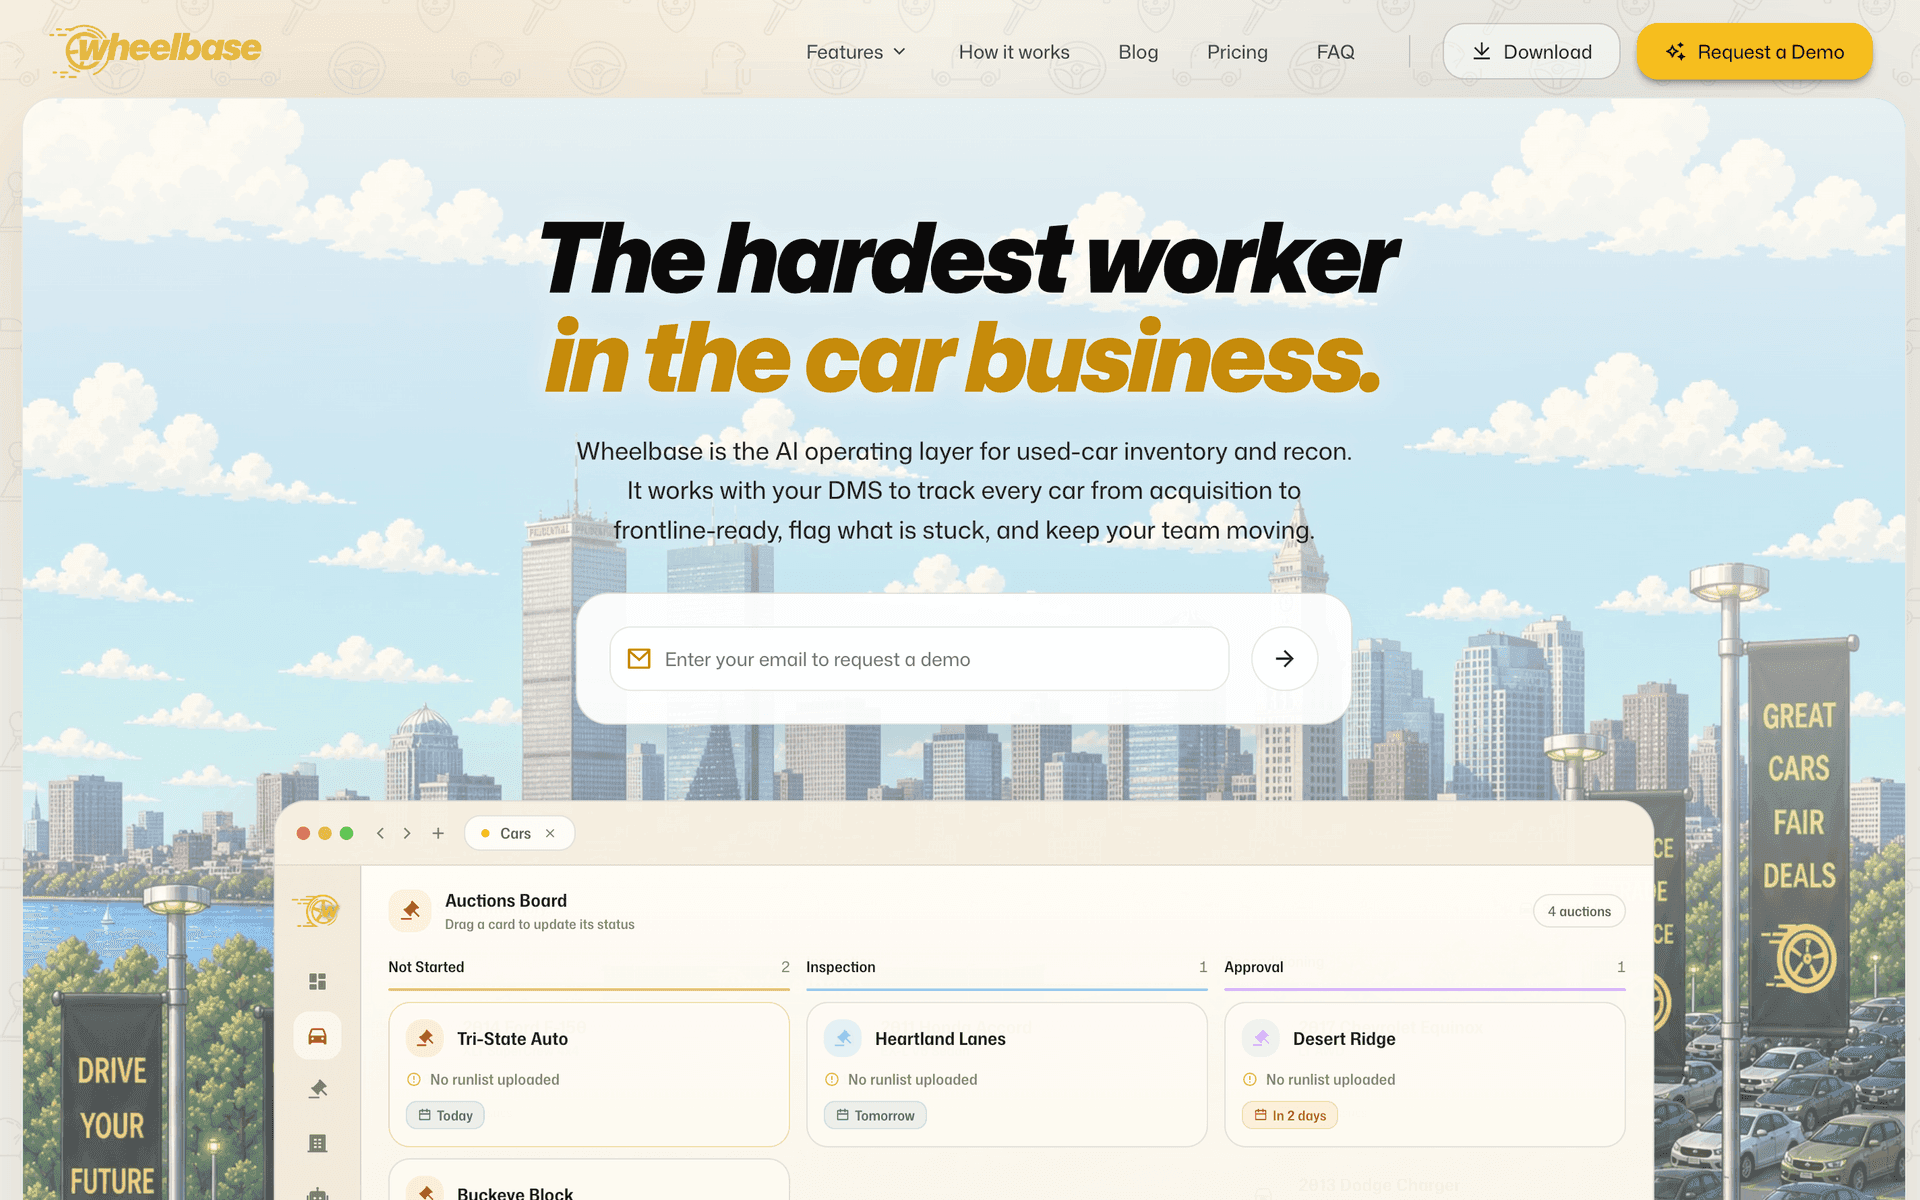
Plate Iwheelbase.io
Wheelbase homepage: The hardest worker in the car business

Wheelbase

2024–Present

Auction intelligence, inventory, and recon for used-car dealers. Hybrid vector search ranks every auction car against real inventory gaps; a governed AI assistant runs the rest.

TypeScript · React · TanStack Start · tRPC · Go

II — Experiments

More projects

  • 2026

    Purser

    A read-only GitHub App that turns each merged pull request into a reviewed changelog draft: dependency bumps and CI-only diffs are filtered out before any model call, then one Claude call writes a customer-facing note, a technical note, a category, and a confidence score. Approved entries push to Slack and an in-app launcher widget, with Stripe plans and Upstash QStash jobs so it runs serverless on Vercel.

    • Never stores diffs; installation tokens minted per request
    • Breaking changes always wait for a human
    • One job path: QStash in production, after() locally

    Next.js · Supabase · GitHub Apps · Upstash QStash

  • Completed

    Global Terrorism Visualization

    Interactive WebGL globe over 177,000+ records from the Global Terrorism Database (1970–2017), plus a seven-view analytics dashboard covering trends, regions, attack types, targets, weapons, and hotspots.

    • Pandas cleaning pipeline: coordinates, NaN imputation, type coercion
    • 8-endpoint FastAPI with analytical aggregations
    • Sampled to 5,000 points to keep the globe smooth

    React · Globe.gl · FastAPI · Pandas

  • Completed

    Teen Phone Addiction Prediction

    Random forest regressor predicting adolescent phone-addiction risk from behavioral survey data, tracked with MLflow and served through a FastAPI endpoint that always loads the latest registered model, with a Streamlit dashboard for exploration and live prediction.

    • Every run logs params, seven metrics, and the model artifact
    • API auto-serves the newest registered model
    • Streamlit EDA and feature-importance playground

    Python · scikit-learn · MLflow · FastAPI

  • Completed

    SkinGuard

    Binary skin-lesion classifier (benign vs. malignant) trained on 10,015 HAM10000 dermatoscopic images, with four training pipelines across TensorFlow and PyTorch and export to Apple Core ML for on-device iOS/macOS inference.

    • Custom CNNs, class-balanced 224×224 pipeline
    • MLflow tracking of per-epoch loss and accuracy
    • Core ML .mlpackage export via coremltools

    TensorFlow · PyTorch · coremltools · MLflow

  • Completed

    Procmon ↗

    A minimal, htop-inspired process monitor in C++17 with an ncurses UI, reading live process data straight from the Linux /proc filesystem and refreshing every second.

    • Process / System / UI layers composed by dependency injection
    • POSIX directory traversal to enumerate PIDs
    • cmdline → comm → [unknown] fallback for kernel threads

    C++17 · ncurses · POSIX · procfs

contributions in 532 contributions in the last year

Darker squares mean more contributions. Levels: no contributions, 1 to 7 contributions, 8 to 13 contributions, 14 to 20 contributions, 21 or more contributions.

III — Open source

A clearer error in pandas

Plotting a frame with duplicate column names told you there was no numeric data, even when every column was numeric. The real cause was in MPLPlot.__init__: with non-unique labels, data[col] returns a DataFrame instead of a Series, is_numeric_dtype says False, and every column is silently filtered out.

Real duplicate-column support would mean reworking label-based indexing across the plotting pipeline, which the issue itself flagged as a much larger job. So I scoped it: a guard clause before any filtering, and a parametrized regression test for both plot kinds. It merged as submitted.
Repo
pandas-dev/pandas
Closes
#64546
Diff
+11 / −0
Merged
Mar 22, 2026
Before
df = pd.DataFrame({"a": [1, 2, 3], "b": [4, 5, 6]})
df.columns = ["a", "a"]

df.plot.hist()
# TypeError: no numeric data to plot
Fix · pandas/plotting/_matplotlib/core.py
if isinstance(data, ABCDataFrame):
    if self._kind in ("hist", "box") and not data.columns.is_unique:
        raise ValueError("plotting requires unique column names")
After
df.plot.hist()
# ValueError: plotting requires unique column names